NEW AEO Services - Get Found by AI Before Your Competitors Learn more →
NEW GEO Services Now Live — Dominate AI & Local Search Learn more →
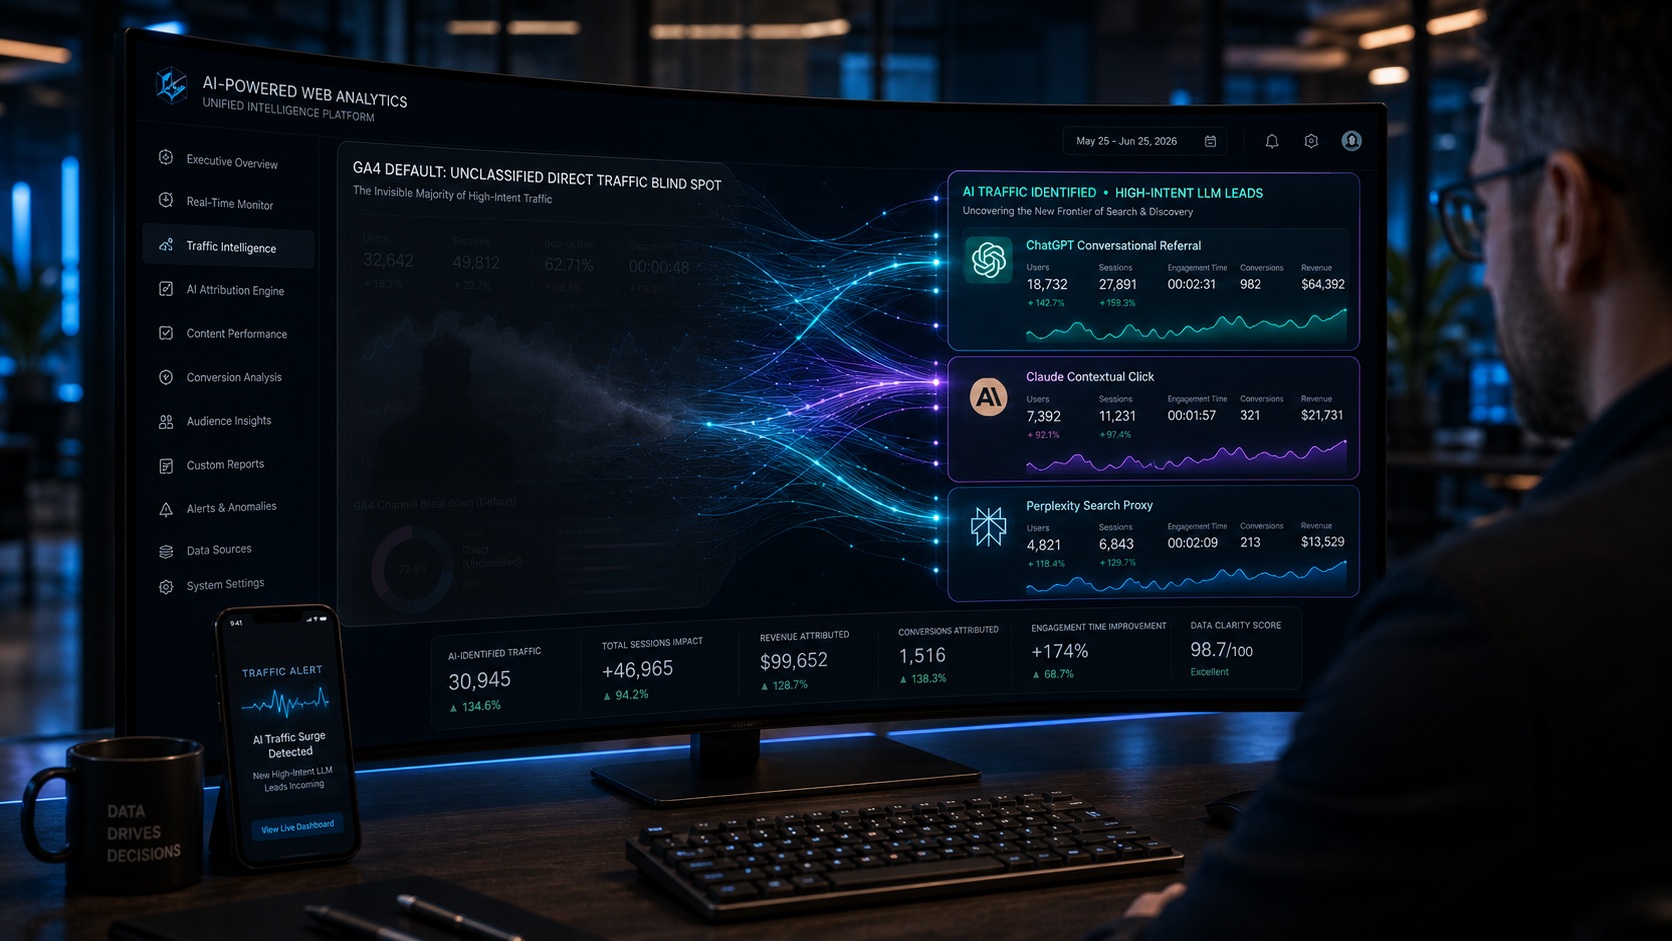
The digital marketing world is changing more radically than since the advent of search engines. People are no longer using regular Search Engine Result Pages (SERP) to search for products, vendors, and answers—they opt for Generative AI platforms like ChatGPT, Claude, Perplexity, and Google Gemini.
This change has created a huge blind spot for brands: dark traffic. More than likely, you are not aware of the buyers with a high intent to buy as a result of large language models (LLMs) searching your website, if you are using the standard Google Analytics 4 (GA4) configuration. This extensive guide explains why there is a tracking gap and offers methodologies you can follow to find hidden leads.
The most common issue with GA4’s misclassification of AI search traffic is due to its infrastructure. GA4 uses data from a digital signature called a referrer header and the UTM parameters to classify inbound traffic.
The two ways the attribution data will split when a user clicks an in-text citation link to visit your website are:
Direct Traffic Dump: Many AI apps run within the context of a closed app or within a secure environment of a website, which removes the referrer header completely (often adding tags such as rel=”noreferrer”).
A session sends no data from Claude or a mobile AI assistant to your website when a user clicks a link. As a result, these highly qualified users are grouped into the “Direct” category without revealing their true source.
When an AI engine is able to redirect its referrer header to the site (like chatgpt.com or perplexity.ai), the default GA4 setup doesn’t interpret it as a search intent. Rather, it pushes it into the general “Referral” channel group along with random blogs, forum mentions, and spam sites.
Since no tracking software can circumvent aggressive browser privacy settings or completely remove referrer strings, you need to use Zero-Party Data: data willingly and directly collected from your consumers.
Use a single question drop-down on your “Thank you” page or CRM onboarding path that asks, “How did you hear about us?” Make additional options available, such as “ChatGPT Search,” “Perplexity,” and “Other AI Assistant” in addition to the standard answers like “Google Search” or “LinkedIn.”
This change towards AI-powered search is not a fad or a temporary trend but a significant reorientation of how consumers are searching for and engaging with brands online. Widely used tracking methods are no longer capturing a significant portion of your leads as AI tools such as ChatGPT, Perplexity, and Claude are gaining a significant share of the high-intent search traffic.
Yes. According to early B2B SaaS and enterprise data, verified AI search traffic can convert up to 3x to 5x faster than traditional organic search. This is because the user has already gone through a multi-step conversational qualification process within the LLM prior to clicking through to your domain.
No, since training bots don’t invoke the GA4 tracking scripts. Raw HTML server data is scraped by bots, such as GPTBot or ClaudeBot, but they don’t run any client-side JavaScript, and they don’t affect your click analytics, bounce rate, or session counts. Blocking training bots should only be done if you have proprietary information you don’t wish to be exploited in future LLM models.
The training of bots, like GPTBot, involves collecting huge amounts of historical web text data to help develop the core intelligence of future AI systems. Citation bots (such as ChatGPT-User, Perplexity-User) are search proxies that operate in real-time. If the user asks an LLM a time-sensitive question, the citation bot instantly goes to live web links to fetch updated information and sources.


 +91 9836 720 921
 +91 9836 720 921
 saha@zenithsolz.com
 soumya.seo@outlook.com


